


UAE
Testvox FZCO
Fifth Floor 9WC Dubai Airport Freezone
 BY
Testvox
A product team ships a support chatbot. Someone tries a dozen prompts in the playground, everyone nods, and it goes live. Three weeks later, the bot is confidently inventing a refund policy that doesn’t exist, and nobody notices until a customer takes the company to a tribunal over it.
That’s not a hypothetical. It’s close to what actually happened to a major airline, and it’s the exact failure mode an LLM evaluation testing framework is built to catch before it reaches a real user.
Manual prompt checking feels like testing. It isn’t, not in any sense that scales past a demo.
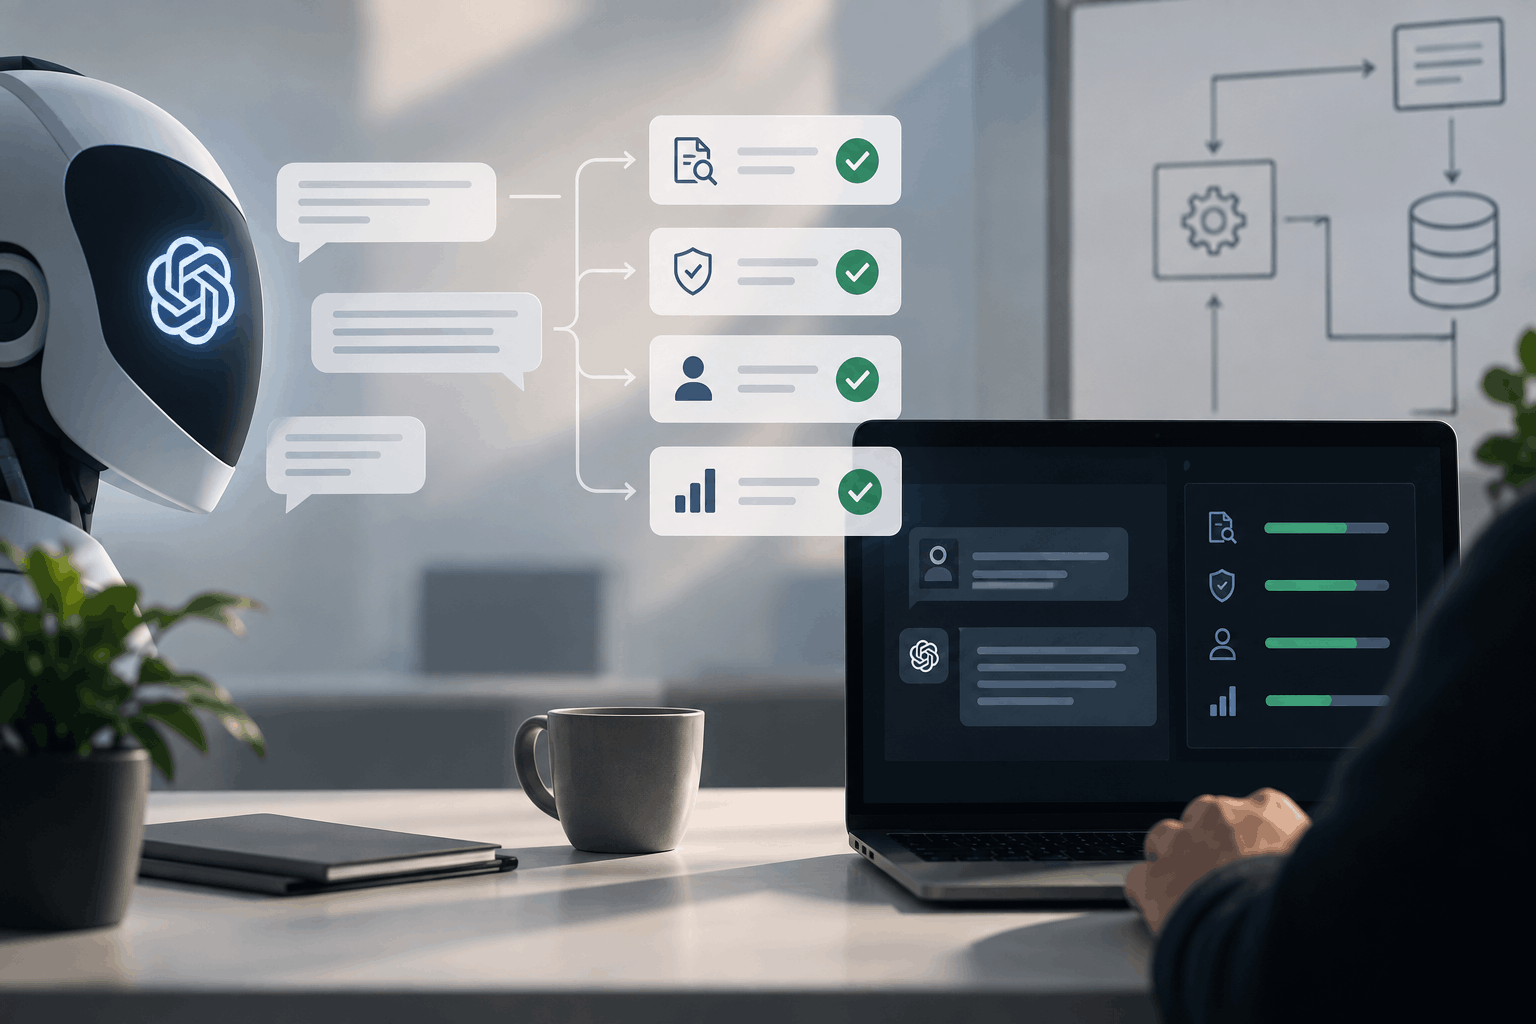
An LLM evaluation testing framework is a structured, repeatable process for testing whether an LLM-powered feature’s outputs are correct, safe, and useful. It combines automated metrics, LLM-as-a-judge scoring, and periodic human review, replacing the ad hoc “try a few prompts and see” approach that can’t catch regressions once a feature is in production.
Traditional software testing assumes a function returns the same output for the same input every time. LLMs don’t work that way.
Run the same prompt twice and you can get two different, both plausible-sounding, responses. A broken function throws an error and blocks your pipeline. A broken prompt returns a clean response, valid JSON, correct status code, and content that is quietly wrong.
No alert fires. The feature keeps running. Users just start trusting it a little less each time.
This is also different from reviewing AI-generated code, where a human is checking logic a model wrote. Here, you’re testing the model’s live output to real users, continuously, which is a distinct testing problem from code review even though both involve AI in the loop.
An LLM evaluation framework is a structured, repeatable way to test whether an LLM-powered feature’s outputs are accurate, safe, and useful. It combines automated metrics, LLM-as-a-judge scoring, and human review, instead of relying on ad hoc manual prompt checks that don’t scale or catch quiet regressions.
Strip away the tooling and terminology, and a good eval suite is answering three things for every response your feature generates:
A response can pass a factual accuracy check and still fail the user completely.
This framing matters because it’s easy to build a suite that only checks correctness and misses the other two entirely. Testvox has covered the broader philosophy of testing AI features earlier in the pipeline in this piece on shift-left testing for AI agents, which pairs well with the tactical detail here.
Most real-world eval suites combine several of these, not just one.
Metrics like BLEU, ROUGE, BERTScore, and exact match compare generated output against a reference answer mathematically. They’re fast and cheap to run at scale, but they’re blunt instruments; they can penalize a correct answer that’s phrased differently from the reference.
A separate model scores outputs against criteria you define in plain language, often producing both a score and a short explanation of its reasoning. Research on this approach has found scores correlating reasonably well with human judgment, which is why it’s become a practical industry standard for evaluating open-ended output at scale.
You maintain a set of known inputs with verified correct outputs and run your feature against them regularly. This is especially useful for catching regressions after a prompt, model, or retrieval change.
Even with strong automation, periodic human review of a sample of real outputs catches things automated methods miss, especially subtle tone, cultural context, or edge cases nobody thought to test for.
If your feature retrieves information before generating a response, a common pattern for support bots and internal search, RAG evaluation testing needs an extra layer on top of everything above.
You’re now testing two separate things:
A model can generate a fluent, well-structured answer that has nothing to do with the documents it retrieved. Groundedness checks specifically catch that gap, which general accuracy metrics often miss entirely.
A workable pipeline doesn’t run every check on every commit. It tiers the work by cost and speed.
Building this kind of tiered process is exactly where dedicated AI testing services earn their keep, since designing the right thresholds and sampling strategy takes real judgment, not just tooling.
In 2024, a Canadian traveler asked Air Canada’s website chatbot about bereavement fares. The chatbot told him he could apply for a discount retroactively, which wasn’t true.
Air Canada refused the refund and argued in the resulting tribunal case that it shouldn’t be held responsible for what its own chatbot said. The tribunal firmly disagreed, ruling that a chatbot is simply part of a company’s website, and the company is responsible for what it says.
This wasn’t an obscure edge case. It was a plausible-sounding, confidently wrong answer to a routine question, exactly the failure mode a golden dataset test covering policy questions would have caught before launch.
Testvox has run into and worked through several of these while testing an AI-powered script writing application, where output quality couldn’t be judged by a simple pass or fail check alone.
Building this well takes more than picking a tool off a list. It takes deciding what “correct,” “safe,” and “useful” actually mean for your specific feature, then building a pipeline disciplined enough to check for all three, every time something changes.
That discipline is what turns an AI feature from a demo into something you can actually stand behind in production, and it’s the kind of structured QA work Testvox builds for teams shipping LLM-powered products.
It’s a structured, repeatable process for testing whether an LLM-powered feature’s outputs are correct, safe, and useful, typically combining automated metrics, LLM-as-a-judge scoring, and human review instead of one-off manual prompt checks.
It’s an evaluation method where a separate model scores your feature’s outputs against criteria you define, often producing both a numeric score and a written explanation. It scales far better than manual human review while staying more nuanced than simple automated metrics.
Traditional testing assumes deterministic outputs, the same input always produces the same result. LLM outputs are probabilistic, so evaluation has to measure quality and correctness across many possible valid responses, not just check for an exact match.
Common automated metrics include BLEU, ROUGE, BERTScore, and exact match for comparing generated text to a reference answer. These are usually paired with LLM-as-a-judge scoring and human review for a fuller picture of quality.
Fast automated checks should run on every code or prompt change. Broader LLM-as-a-judge scoring typically runs on a schedule, such as nightly or before releases, with human review of production samples happening on a regular cadence like weekly.
Shipping an LLM-powered feature without a structured evaluation process is shipping untested code with a friendlier interface. Talk to our AI testing team about building an evaluation suite that actually catches problems before your users do.

GET IN TOUCH
Let us know what you’re looking for, and we’ll connect you with a Testvox expert who can offer more information about our solutions and answer any questions you might have?
